CeresAgents — Code & Showcase
Repository: github.com/GZU-SAMLab/CeresAgents
CeresBench: Benchmark data and annotations
Task-Adaptive Multi-Agent Workflow
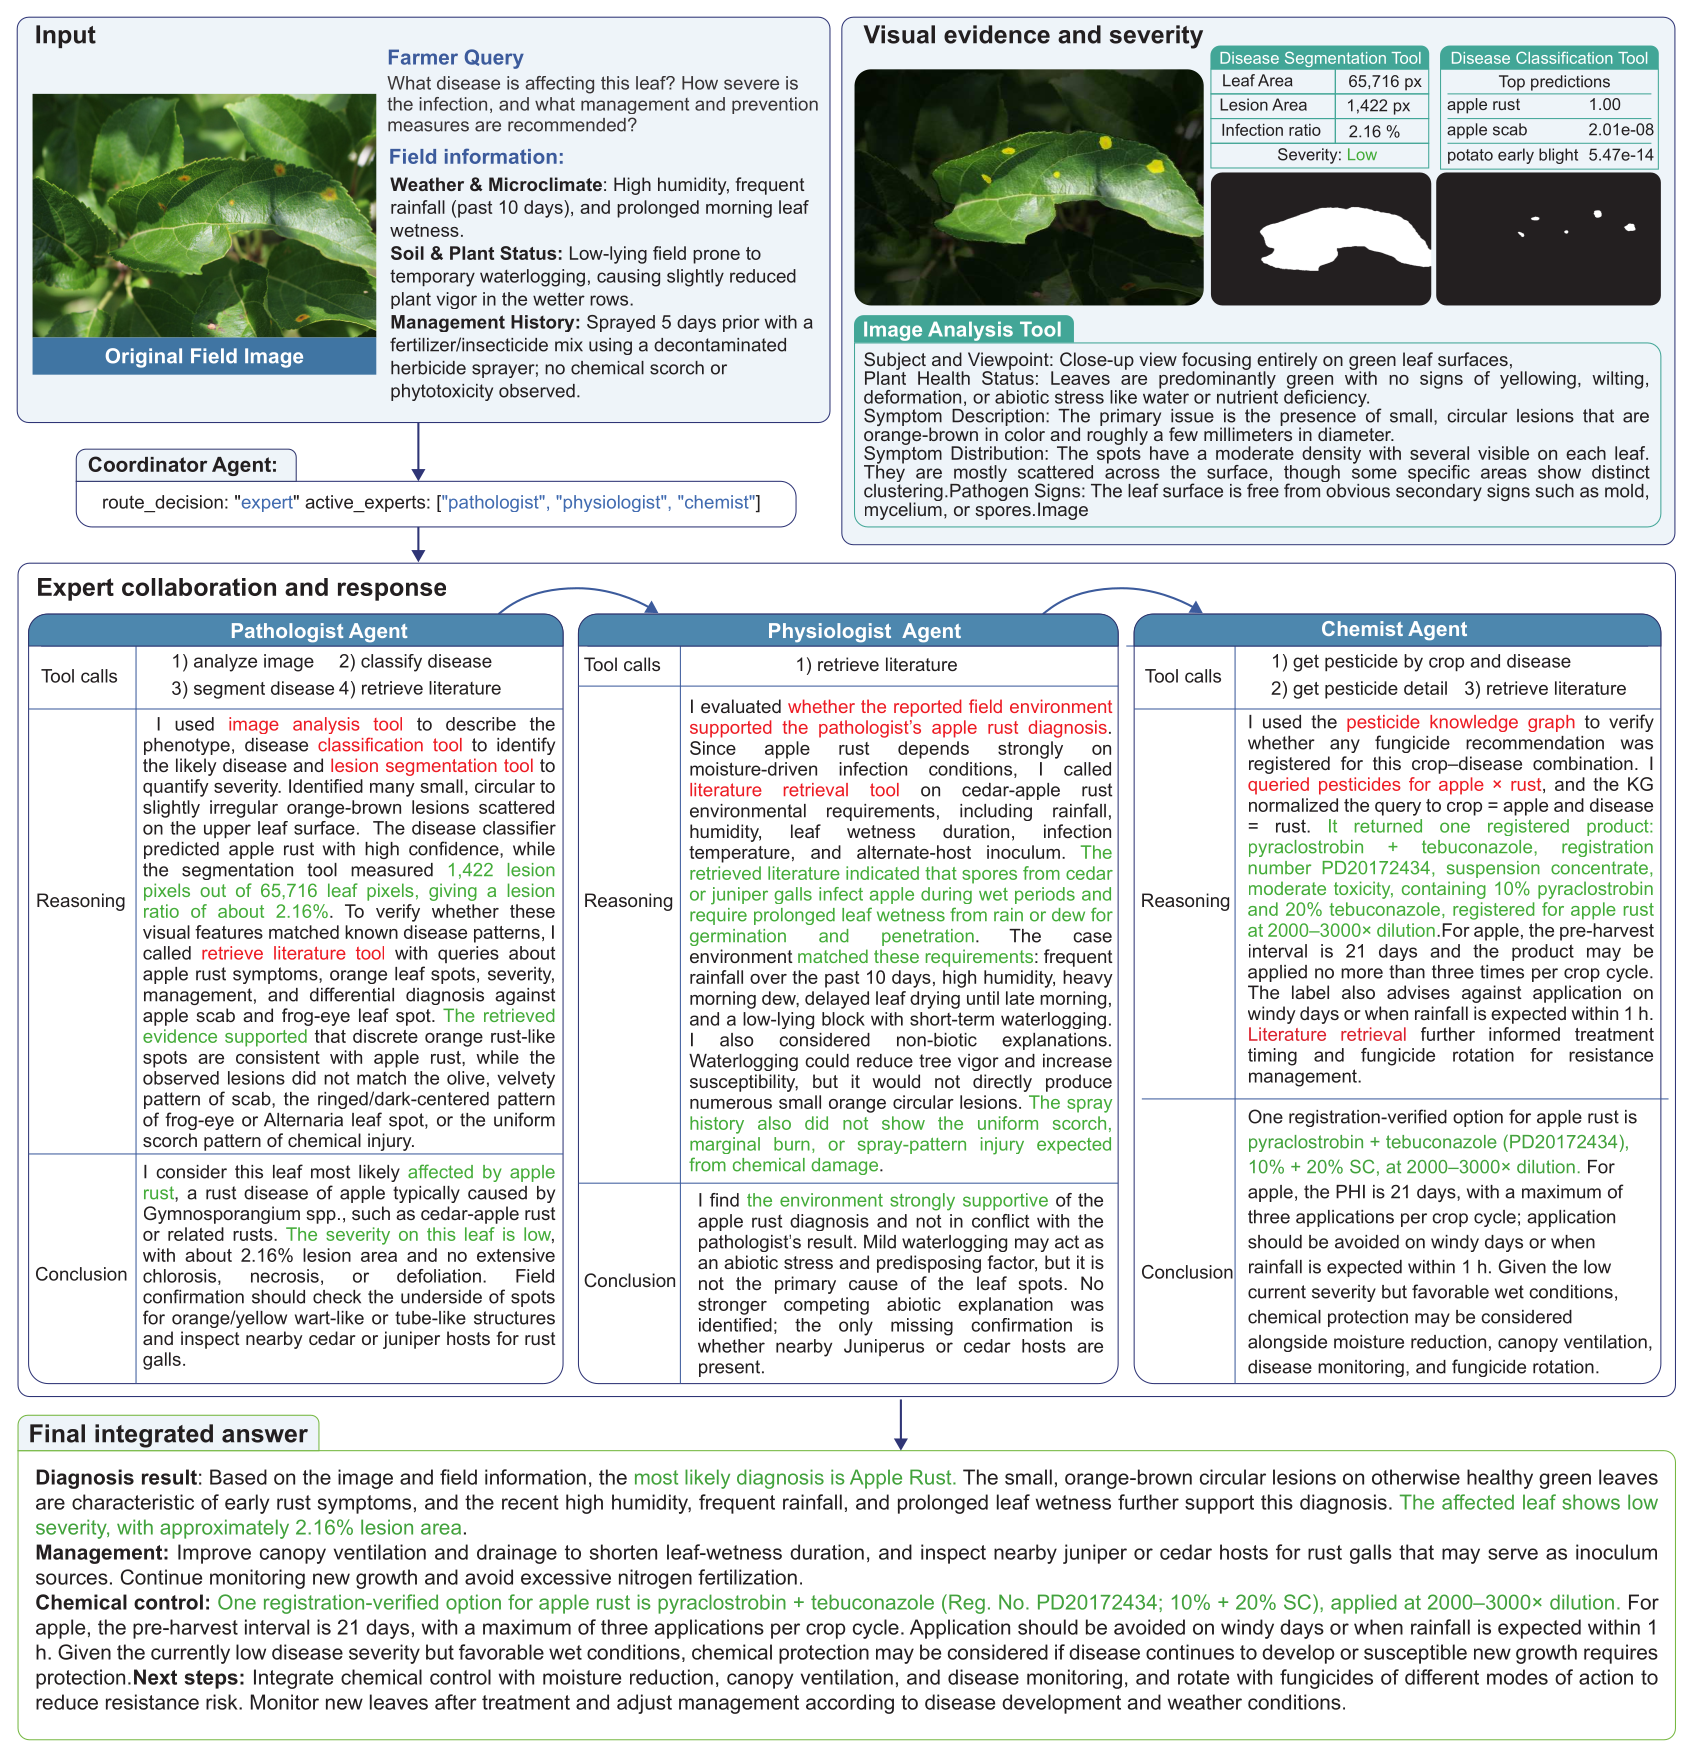
A coordinator standardizes the user query, image, location, environmental context, and management history into a structured consultation state. It then selects either a fast generalist route or an expert route. On the expert route, pathology, physiology, and chemistry specialists address complementary parts of the consultation and exchange findings through a shared blackboard.
User consultation
  ├── Intent-based coordinator
  ├── Pathologist → disease hypotheses and visual evidence
  ├── Physiologist → environmental plausibility and abiotic alternatives
  ├── Chemist → registration, dosage, and label-use verification
  ├── Shared blackboard → evidence exchange and conflict reassessment
  └── Final synthesis → diagnosis, management, safety, and uncertainty
Evidence Resources
The evidence layer combines Qwen3-VL-plus for structured image description, EfficientNet-V2-S for disease classification, separate SegFormer models for visible-leaf and lesion segmentation, hybrid BGE-M3/FAISS/BM25 literature retrieval, and Cypher queries over a Neo4j pesticide knowledge graph.
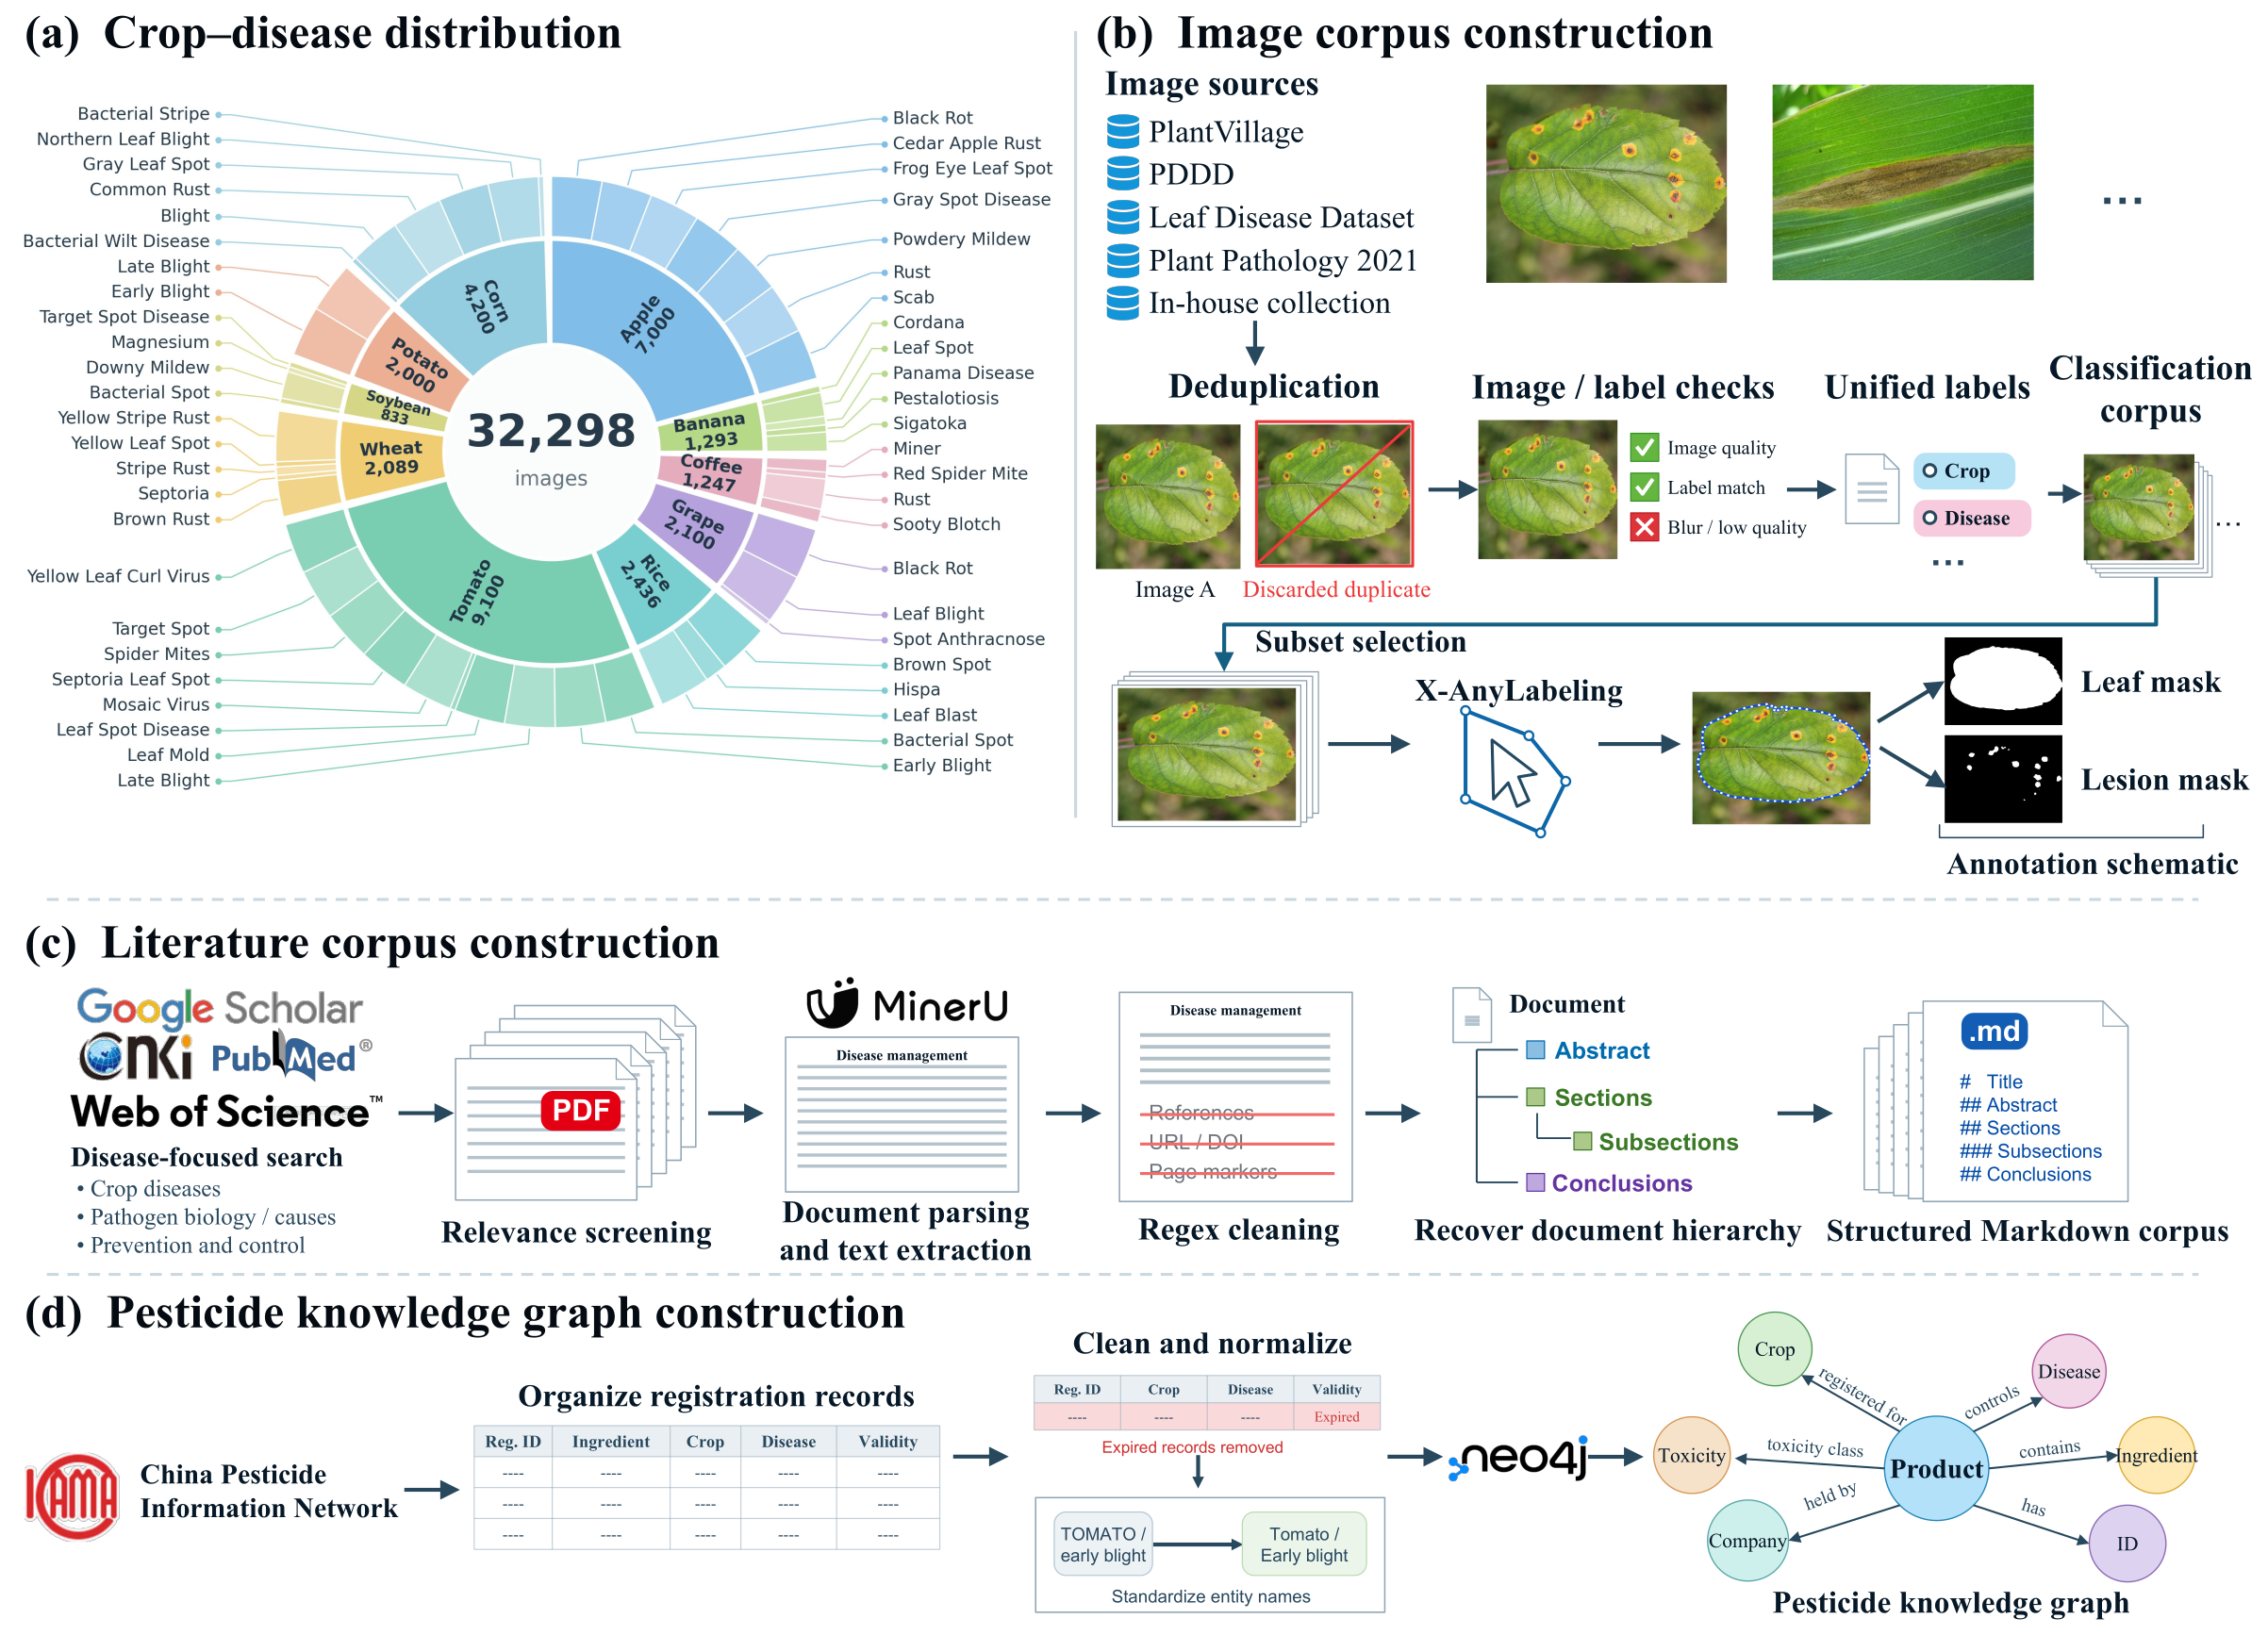
Overall Results on CeresBench
| System | Diag. acc. (%) | Diag. score | Prescription | Safety | E2E | Conflict |
|---|---|---|---|---|---|---|
| GPT-5 | 48.91 | 47.00 | 61.57 | 49.01 | 54.51 | 78.00 |
| Claude-Sonnet-4.5 | 47.45 | 45.23 | 53.62 | 42.77 | 50.56 | 80.00 |
| Qwen3.5-Plus | 61.31 | 58.61 | 64.73 | 54.68 | 62.78 | 77.50 |
| Gemini-3-Pro | 70.07 | 64.60 | 69.82 | 54.53 | 65.19 | 81.00 |
| CeresAgents | 94.89 | 91.67 | 79.93 | 85.13 | 84.60 | 89.00 |
Architecture and Evidence Ablations
| Configuration | Diagnosis | Prescription | Safety | End-to-end |
|---|---|---|---|---|
| Full system | 91.67 | 79.93 | 85.13 | 84.60 |
| w/o RAG | 79.27 | 75.00 | 78.85 | 75.53 |
| w/o KG | 88.59 | 30.43 | 30.92 | 70.27 |
| w/o CV | 64.61 | 69.46 | 66.21 | 63.54 |
| w/o multi-agent | 73.87 | 74.45 | 68.44 | 75.18 |
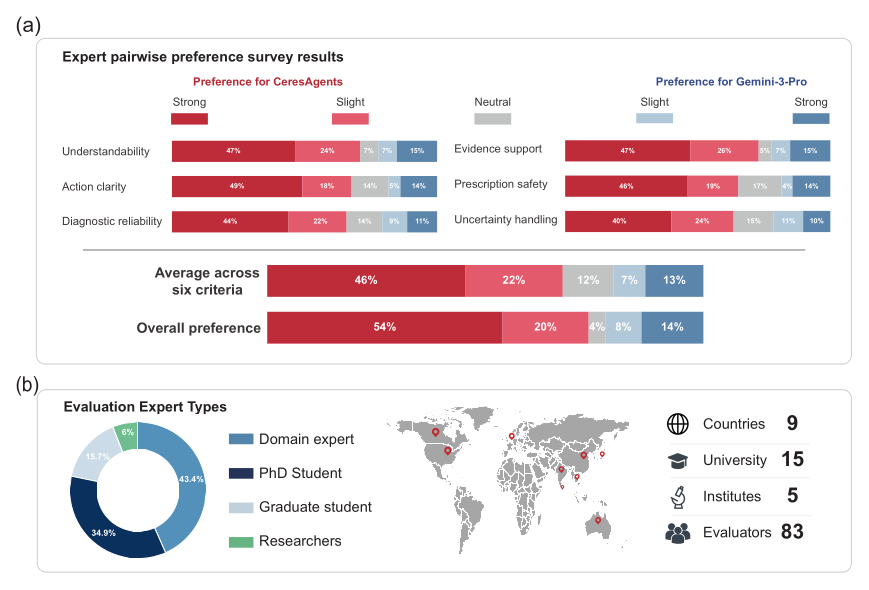
Consultation and Human Evaluation
Code & Artifacts
Code: github.com/GZU-SAMLab/CeresAgents
Benchmark: CeresBench benchmark